Vote to adopt the C++26 draft as the new ISO standard fails
The vote to replace the ISO 2023 C++ Standard with an updated version has failed. Of the 28 P-member countries of SC22, 12 voted Approval, 8 voted Disapproval, and 8 Abstention. At least 66.66% of Approval votes are required (received 60%) and less than or equal 25% of Disapproval votes (received 41%), with Abstention votes not counting towards the total, and Disapproval votes by O-member countries counting towards Disapproval (there was one).
This post discusses the available courses of action over the next 12 months and then looks at factors influencing the continual evolution of the C++ Standard.
Some background for new readers. SC22/WG21, the ISO C++ committee, has been publishing new revisions of the C++ Standard on a 3-year schedule (i.e., 2011, 2014, 2017, 2020, and 2023), and until this setback was going to start work on 2029 at the next committee meeting. WG21 meet three times a year, with the week-long meetings attracting around 200+ people, who have a selection of 23 active subgroups to participate in. On average, there are 108 papers up for agenda time to discuss, and 147 post-meeting papers (average since 2024). This is industrial scale document processing.
What motivates 200+ people to regularly attend a gruelling week-long session of detailed technical C++ discussions? I have long said that the C++ committee has become a playground for bored consultants looking for a creative outlet. There are also the speakers and consultants who make their living talking about what’s new in C++, and giving training courses on the latest features of the language. The implementors are a tiny, but influential minority, because there are not many implementations. The energy driving WG21 comes from the people who attend. The bored consultants want their pet language feature adopted into the C++ standard, the speakers/consultants need something new to talk about, and the implementors need new features to be paid to implement (hopefully; funding is tough). WG21 is its attendee’s gravy train.
Nobody inside WG21 wants the gravy train to stop, so what happens next?
When a country votes Disapprove, they are required to specify what action the committee needs to take for them to change their vote to Approve. Removing contracts from the draft is what is required to turn the majority of Disapprove votes to Approve (various editorial issues were also requested by various countries). Contracts almost made it into the 2020 Standard, but was withdrawn at the last minute.
The WG21 committee has two options, and their next meeting starts in 2 weeks, 16th November, in Brazil:
- agree to remove contracts, and vote to send the revised draft for another DIS (Draft International Standard) ballot at their March 2027 meeting (or June if the editorial work is not complete by March). The ISO directives specify that a second DIS ballot lasts 12 weeks, so the current draft minus contracts would be published around the third quarter of 2027, at the earliest. These directives also specify that a committee can only make changes that address Disapprove comments and cannot do any work revising a draft that is out for ballot.
The bored consultants have already spent almost a year sitting on their hands, while the current draft standard went through the (failed) approval process. Will they be willing to spend another year without their fix of C++ bike shedding?
- skip to C++ 2029, i.e., not submit a contractless draft for voting, so C++ 2026/7 does not happen.
This immediately restarts the gravy train. If the supporters of contracts believe that the existing wording can be tweaked to make it broadly acceptable, they might not be willing to see it removed from the draft.
How contentious is the current specification of contracts? The 8 Abstentions is rather telling. Eight countries with people actively involved in WG21 work failed to reach consensus, including the US (the convention is for countries without active participation to be polite and vote Approve). Stroustrup, as a member of the US delegation, voted against the proposal, and has said (53 minute mark) “…it’s claimed to be a minimal viable product. It’s not minimal, it’s not viable.”
Contentious issues sometimes take many meetings to resolve. An extreme case is the 13-years before Fortran-77 became Fortran-90, with meetings described as “… two major vendors against the majority of X3J3 [ANSI Fortran committee] …”
One of the jobs of the chair of WG21, before forward a document for DIS balloting, is to be confident that consensus has been achieved. There was a change of committee chair at the start of this year. Even so, he is going to be in the hot seat at the next SC22 meeting.
What of the longer term future of work on the C++ Standard?
For some time I have been saying that WG21 is past its sell by date. The supporters of 3/4 industrial C++ compilers could meet together to agree new language features and their semantics, just like ECMAScript (aka JavaScript) and Java.
However, work on standards is controlled by those who do the work. If enough people continue to turn up at WG21 meetings and write papers, then the C++ Standard will continue to evolve. Cobol 2014 looked like it would be the final standard for the language, but as retirees like to say “I just had my eyes closed”, and we now have Cobol 2023 (the COBOL front end for gcc, which now supports COBOL 85).
The availability of LLMs creates two threats to established WG21 work practices, and a potential benefit.
- The committee was straining under the volume of submitted papers, proposing changes, before LLMs arrived. Now that the effort needed to write and format a proposal has been significantly reduced, the number of papers submitted is likely to increase. While voting was underway, there were 116 papers in the May 2026 pre-Brno mailing, of which five acknowledge LLM assistance, thirty are very likely have had LLM assistance (according to Devin), and three possible uses of LLM,
- the wording of the requirements in the C++ Standard has always been somewhat lax and open to interpretation (speaking as someone coming from a C Standards background, where there is a lot less ambiguity). Previously finding inconsistencies and ambiguities in the Standards’ document required a broad and deep understanding of that document. LLMs have removed the need for a broad/deep understanding of the language. If somebody were to decide to reduce the inconsistencies/ambiguities in the C++ Standard, they could use LLMs to submit a stream of issue requests, whose impact would be to overwhelm the current process, which currently has around 100 new issues added annually to the language issues list and around 250 added annually to the library issues list (averaged over the last few years),
- coding agents provide a mechanism for removing a ball-and-chain that restrains all programming language committees (the compatible with C ball-and-chain was dropped in 2018). Compatibility with existing code, which conforms to the existing standard, is an oft cited reason for not changing existing behavior specified by the standard. Coding agents could significantly reduce the cost of updating existing code to handle changes to the semantics of C++. I’ll skip over the issue of how coding agents are trained on new language/library semantics, given that the only examples are contained in the proposal paper(s).
Given the expanding creative abilities of coding agents, the number of bored consultants is likely to grow. There will be a C++ 2032/3, whether the world wants/needs it or not.
Mutating Lean proofs looking for issues
A common technique used to bolster confidence that LLM derived proofs of mathematical statements are correct is to supply an associated machine checkable form of the proof written in the Lean language, i.e., a program that can be interpreted by the Lean proof assistant.
Mathematicians have discovered, shock horror, that LLM generated proof-programs contain bugs. Given the current trajectory of mathematical work, perhaps it should now be considered a field of software development (developers have long known that LLM generated code contains bugs).
Coding agents can generate programs that appear to work, while containing code having undesirable consequences (e.g., security issues) and surprising hallucinations, and it is only to be expected the generated Lean programs will contain these features. What can be done to check Lean programs for coding mistakes?
The traditional approach to finding issues with source is to read it. Lean proofs can contain many thousands of lines, and depending on your background be more/less easy to read than most programming languages. Reading Lean is the expensive, time-consuming, high value option. The source of an example Lean theorem is below:
theorem core_cycle (t : Nat → Nat) (h₀ : t 0 = 7) (h₁ : t 1 = 4) (h₂ : t 2 = 9)
    (hp : ∀ n, t (n + 3) = t n) : t 2019 + t 2020 = 11 := by
  have step : ∀ k, t (3 * k) = t 0 ∧ t (3 * k + 1) = t 1 := by
    intro k
    induction k with
    | zero => simp
    | succ k ih =>
      have e1 : 3 * (k + 1) = 3 * k + 3 := by omega
      have e2 : 3 * (k + 1) + 1 = (3 * k + 1) + 3 := by omega
      constructor
      · rw [e1, hp]
        exact ih.1
      · rw [e2, hp]
        exact ih.2
  have h2019 : 2019 = 3 * 673 := by decide
  have h2020 : 2020 = 3 * 673 + 1 := by decide
  have a : t 2019 = 7 := by
    rw [h2019, (step 673).1, h₀]
  have b : t 2020 = 4 := by
    rw [h2020, (step 673).2, h₁]
rw [a, b] |
One automated process that might be used to find suspect usage is mutation testing (which was once consigned to the grave). The idea is to mutate (e.g., make a non-trivial change) to the Lean source, and then check whether the mutated proof still validates. The assumption is that proof source that can be substantially mutated without changing its verification status is suspect.
Yesterday I took part in the Noetic X Nebius One Day Hackathon, and Team MutationHacker (Jacky Chen, yours truly, and Claude Open 5.5) worked towards creating a tool to automatically mutate and check Lean proofs.
Our grandiose plans were undermined by a submission deadline of 16:00 (we had around 5-hours). An agent based system that learned from past successful mutants was replaced by the MVP of a python program running on a laptop picking mutations at random and running the Lean verifier on the laptop (not fast). Successful mutants (i.e., no change to verification state) accumulated in the proof source.
How many mutants can a Lean proof of a theorem accumulate, and still verify, before it’s considered suspect or problematic? The mutation tool managed to add 13 mutants to the small test case that we used. I have no idea how representative this is.
The mutant generator specification lists of constructs not to use, e.g., changes that had no effect on the rest of the proof.
Perhaps the Lean source contains dead code, or bounding conditions are overly wide, e.g., can be replaced by
 .
lean-bugs is available on GitHub.
Ideally many thousands of mutants are tried, but the time taken to verify a short proof is several seconds, which will require lots of cpu time to check thousands of mutants. There don’t appear to be any benchmarks comparing Lean performance for various proof sizes (the timings cited don’t appear to connect to what I am after).
OpenAI’s recent Navier-Stokes solution came with 470K LOC of Lean which has been verified by independent researchers in times ranging from 212 seconds to 15 minutes. The smaller precursor theorems and lemmas could be mutated as stand-alone items, to reduce overheads.
Program to extract x/y coordinates of points in pdf graphs
There are two techniques for specifying the display information contained in any graph within a pdf file. Raster graphics specifies (e.g., jpeg and png formats) the location and color of pixels, and vector graphics specifies (e.g., pdf and svg) the x/y coordinates of shapes/colors on the page. With vector graphics it’s possible to calculate the graph-axis relative positions of displayed symbols using the page relative x/y positions of each symbol (denoting a measurement point), the graph axis and axis tick marks/values; something I first did out in 2013. My Evidence-base software engineering book contains 10+ datasets that have been manually extracted from vector graphics within pdf files, i.e., by writing a graph specific awk script (a summary of the processes and tools used).
Can coding agents be used to implement a program detects and extracts the x/y coordinates (axis relative) of data points in any graphs, implemented using vector graphics, contained in a pdf file?
Do LLMs know of any tools that already do this? No.
This weekend I attended the Reinvent the Wheel: A Tools for Science Hack, where attendees were given credits for a month of Claude Max (these days I don’t write enough code to make it worth spending more than $20 per month on subscriptions). This was a perfect opportunity, and motivation, to create a specification of the data point x/y coordinate extraction process, and then to attempt to get a coding agent to generate a python program that extracted this data from any pdf file (whose plots were created using vector graphics).
Data points within a graph are drawn using a variety of symbols, and the symbols are drawn using a variety of techniques. For instances, a circle might be drawn using a single internal pdf instruction, drawing four quadrants using Bézier curves, or even eight Bézier curves, or who knows what (it’s very frustrating).
Then there are the tick marks along the axis, some of which are labelled with numeric values, don’t always start/finish at the ends of the axis, and denote a scale that could be linear or logarithmic.
My plan was to specify what was required, briefly describe the internal organization of a pdf file, provide a pdf file containing a single graph and the corresponding extracted data, as a csv file, and see what happens.
The start of my conversation with Claude Opus 5.5 follows:
Write a python program that takes as input a pdf file and outputs the x/y coordinates of individual data points displayed using vector graphics. The vector graphics, as specified by internal pdf instructions, used to display these data points appear on lines bracketed by lines that just contain the words "stream" and "endstream" The data points appear within a graph displayed on a page. This graph contains an x and y axis and may contain other unrelated lines and text within the plot's x/y axis. The required x/y data point coordinates must be relative to the values displayed on the plot's x and y axis. Each x and y axis is drawn as one long line and short tick marks for particular axis values. An internal instruction is used to display a numeric value close to its associated tick mark. Various symbols may be used to display each data point. For instance, in the attached pdf file a data point is denoted by a circle created by joining four bezier curves. The required x/y coordinate is at the center of the approximate circle drawn by these four bezier curves. All data point coordinates must be output, even data points having the same x/y coordinates as other data points. The attached file schump.tgz contains a pdf file and a csv file containing the internal x/y positions of the data points and the corresponding graph relative x/y positions, it also contains the page number and the color of the data points. Each graph is numbered. |
It took about 15 minutes to create a python program that extracted the information from the pdf file that matched the contents of the csv file. I was impressed.
The generated program was then extended one feature at a time by describing some possible characteristics of a graph, and attaching a pdf containing a graph containing those characteristics; for instance (another 15-20 minutes):
Extend the program to support data points displayed as a diamond shape created by drawing four lines. The attached file 53cfc681e8e2afa9feb5820f4886e3018005-009.pdf is a pdf file. The data points are denoted by diamonds created by drawing four short lines. |
This one/two feature at a time iteration looped six or so times before I grouped the remaining features into one update. Two+ hours later Claude provided 4K+ LOC of python code that appeared to handle everything.
The most impressive behavior was spotting minor issues that I had not mentioned and supporting them, or asking if they should be supported.
The pdfgraph2csv GitHub repo contains the code + regression tests.
Is the information in the output csv files correct?
The x/y coordinates of the points in the graphs in my book are available to be checked against. I also plan to repeat the process using a coding agent from another vendor, and to compare the contents of the corresponding csv files. N-version programming, here we come.
Programming language choice is becoming a build option
What significant problems do high-level programming languages solve in a world of coding agents?
The original rationale for using high-level languages was to reduce the cost of porting existing software to different platforms. In a coding agent world, this is a benefit for those interested in having their software run on more than one platform. Is it a worthwhile benefit for those running on just iOS and Android (Shopify recently switched to a common codebase in React Native)? A general answer to this question will have to wait until things have settled down, some years from now.
Some software systems have configuration options that are selected at compile time. Having coding agents generate all possible option configurations is only practical when there are only a few possible combinations. The Linux kernel contains around 15,000 options, and while many of the  possible option combinations are unrealistic, just 243,323 combinations produces a huge variety of executable programs. The source code approach is the only workable approach when many compiler time options need to be supported.
Existing practice is that program source code is written in a high level language, which is then translated to an executable form. Generating source in the programming language(s) being actively used enables coding agents to be seamlessly integrated into existing practices.
In specification based programming, English (or another human language) is the language used to create software. The actual programming language used when generating source code is not yet irrelevant.
Various kinds of activities are reviewed during the development of a software system. These include: requirements review, design review, code review, test review, and acceptance review.
Source code is needed for code review, which is frequently talked about but infrequently performed (an analysis of evidence; see section 6.6.1 for a summary of practices). Code review is a great mechanism for synchronizing practices within a team, training new developers and generally keeping team members up to date with what others are doing. These are benefits that apply when software is written by people. When source is generated by a coding agent, why do people need to review it? The reasons I have heard involve issues covered during requirements and design reviews. Another coding agent might check the code looking for mistakes, and this could be labelled as a (non-human) code review.
If the generated source is not going to be read by people, does it matter which programming language is used to generated it?
Coding agents require source code for training, and this is available in a variety of programming languages. Quantity of source code training data has a significant impact on LLM performance. Generating source in the language most likely to elicit the best coding agent performance is the obvious answer.
Choice of programming language is sometimes driven by current fashions, happenstance or a particular belief system. For instance, the conversion of existing non-Rust source to Rust is driven by the current fashionably status of that language, along with the effectiveness and low cost of coding agents.
Programming languages choice is evolving in to being a configuration option.
I’m sure that eventually somebody will convert the Linux kernel to Cobol and build a running system. As a start, I used the Devin coding agent to convert the contents of the kernel init directory to Cobol source and Fortran source. Both sets of source compile, but don’t link against any other kernel object files.
Before coding agents hackers were content to create their own new Linux distribution. To be leading edge in the future, a hacker will need to translate the Linux kernel and/or distribution to a language of their own creation (LLMs are now building compilers).
Single-handedly creating/implementing a language and using it to implement an operating system used to be a niche activity. First released in 2005, Terry A. Davis single-handedly wrote TempleOS in a language he created and implemented called HolyC, driven by a revelation from God. In the coming years, I expect to see many of these belief driven projects.
Impact of input distribution on faults experienced
The impact of user input variability on number of reported faults is an important issue that is rarely researched. Appropriate user input is one of the three events that needs to occur for a software system to experience a fault. Program fault reports are caused by its users.
I am not aware of any published studies providing the evidence that a change in the distribution of program input values does indeed produce a change in the number of faults experienced. However, the supporting material of a recent paper on N-version programming contains everything needed for me to provide the evidence.
The paper N-Version Programming with Coding Agents by Ron, Baudry, and Monperrus [RBM] uses coding agents to create many implementations of the same specification.
The specification is for a missile tracking simulation program, and the input is a set of (x, y) coordinates representing two-dimensional radar tracks. The program is required to decide whether the set of points meets a combination of 15-conditions for the detection of an incoming missile, whose detection would cause the launch of an interceptor missile. Previous analysis of the RBM data.
In the RBM paper, for testing, the set of (x, y) values were randomly drawn from a uniform distribution, within bounds [-100, 100]. Drawing the (x, y) from a different distribution should cause the number of detected faults to change. I modified the test generator to use a triangular distribution. The mode (i.e., the peak) of the distribution was at: -90, 0, or 90 (the distribution is symmetric, so the results should be the same for -90 and 90; in practice they might not be {they were}).
The initialization loop at line 117 in the file generator.py was modified to call rng.triangular; for instance:
# x = [float(v) for v in rng.uniform(-100, 100, size=numpoints)] # y = [float(v) for v in rng.uniform(-100, 100, size=numpoints)] x = [float(v) for v in rng.triangular(left=-100, mode=0, right=100, size=numpoints)] y = [float(v) for v in rng.triangular(left=-100, mode=0, right=100, size=numpoints)] |
The plot below shows the three triangular distributions used, and a uniform distribution (code+data):
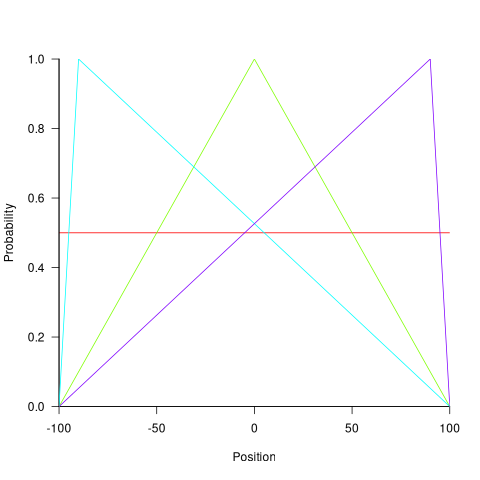
Changing the distribution of the generated points changes the average distance between two randomly chosen points. Given that the 15-conditions involve: the distance between consecutive pairs of points, and three consecutive points fitting within a circle of a given radius, a change of average distance will change the number of detected incoming missiles.
The table below shows the mean distance between two points when the (x, y) values are randomly chosen from the corresponding distribution (LLM derivation), and the corresponding normalised failure rate for three of the generated programs (replicating the original 1-million tests with four of the generated programs; code+data):
x distribution y distribution Mean distance Failure rate Uniform Uniform 104 1.0 Triangular mode 90 Uniform 93 1.9 Triangular mode 0 Uniform 89 2.0 Triangular mode 90 Triangular mode 90 82 3.6 Triangular mode 90 Triangular mode 0 76 3.7 Triangular mode 0 Triangular mode 0 73 3.9 |
The failure rate is normalised to that for the Uniform distribution. The increase in failure rate, as the mean distance between points decreases is a consequence of the particular coding mistakes in the generated programs. Different coding mistakes could produce a decreasing failure rate with distance (it decreased for the python implementation tested, but the rate did not change with distance)
The RBM study used a random number seed of 42. The maximum difference in number of detected faults, for a uniform distribution, when using seeds of 42, 202, 321, 789, 6000, and 20101 was around 10-20%. Changing the distribution had a significantly larger impact than changing the random number seed.
LLM handling of programming language differences
LLMs are trained on the publicly available source code, with no consideration given to the programming language used. There is an implicit assumption that training on code written in X and Y, rather than just Y, produces an LLM that does a better job of generating code written in Y.
To what extent will the characteristics of the training data from language X source ‘leak’ into source code generated for language Y?
LLM source generation is a very new field and significant improvements are still being made to models and agent harnesses. This article lists some issues, and checks how a few models handle them.
It would be great to have lots of LLM generated code to measure, and there are a few collections of LLM generated code. However, reliably distinguishing human from LLM generated code is an open problem. A 2025 study of Python source generated by multiple LLMs found that it was not possible to reliably predict human/LLM authorship (which suggests that LLM source datasets collected using authorship prediction are likely to be unreliable). The characteristics of a dataset of individual functions are unlikely to have the same distribution as a dataset of complete programs.
Some language usage behaviours are the result of the widespread adoption of particular conventions, and from the program correctness perspective these differences are harmless (e.g., source indentation), while others are semantic differences that could produce different output.
While patterns caused by coding conventions might not change
program output, they can change its performance characteristics (e.g., larger functions can alter cache occupancy), and some of these patterns are input to mathematical models of program evolution, e.g., distribution of method size (in LOC) is a factor in modelling the percentage of methods containing no reported faults.
The plot below shows the percentage of C/C++ (same behavior) and Java functions/methods containing a given number of lines (data recently extracted using CodeQL’s variant analysis of 100 C/C++ and Java projects, with 1,094,911 C++ functions, 328,009 C functions and 4,506,326 Java methods; code+data):
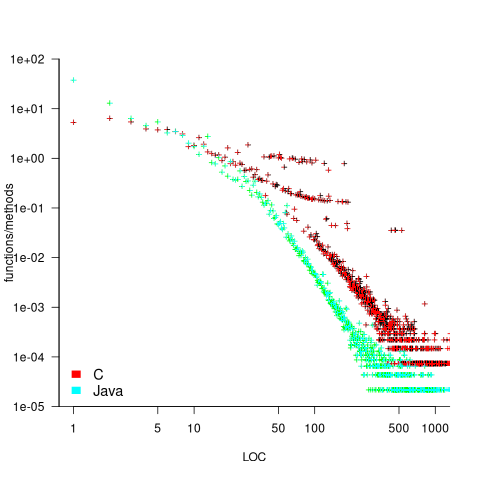
The large number of 1-line Java methods is assumed to be due to the widespread use of getters/setters. For the most common function/method sizes (i.e. 1 to 10 lines), have C and Java very different distributions, but follow a very similar power law for more than around 50 lines. Will LLM generate code contain this C/Java size difference, or will it have a completely different distribution (coding agents do seem to generate more code)?
Pre-object-oriented algorithmic languages can be classified into two families, those influenced by Fortran and those influenced by C.
In Fortran arrays are 1-based, while in C they are 0-based. The base-value for arrays is common knowledge, which LLMs handle. The more obscure differences, which rarely occur in source, are more likely to be overlooked.
Fortran and C have differences in operator precedence. The significant difference is the relative precedence of the unary not operator, and the binary equality/relational operators. The expression: ! x == y is equivalent to .not. (x == y) in Fortran, and equivalent to: (!x) == y in C. When asked to convert a C function containing the unbracketed form of the expression to Fortran, both Grok 4.6 and ChatGPT 5.5 note the different operator precedence and insert the appropriate parenthesis.
Both C and Python are popular languages with huge quantities of source publicly available. The token sequence: x < y == y, is parsed as: (x < y) == y in C, but in Python it is parsed as: (x < y) and (y == y). Both Grok and ChatGPT note the different operator precedence and insert the appropriate parenthesis.
There are a variety of differences between C and C++. However, source containing occurrences of all but two of them will produce a compile time error.
The following difference is known in compiler writer circles, and both Grok and ChatGPT note the different possible behaviors:
template_name < a , b > - 5 // equivalent to (template_name < a , b >) - 5) non_template_name < a , b > - 5 // equivalent to (non_template_name < a) , (b > - 5) |
The C/C++ difference that is much more likely to be encountered is the expression sizeof('a'), where C promotes the character 'a' to an int (which commonly has size 4; on DSP processors char often occupies the same number of bits as an int, giving both of them a size of 1), while C++ 'a' has type char (which is defined to have size 1).
There are sometimes behavior differences, for the same source, between versions of the same language specification. For instance, the following somewhat obscure difference between the C90, C99, and C11 language standards:
#include <stdio.h> #define M(U) sizeof(U"s"[0]) int main(void) { switch(M("")*2 //**/ 2 ) { case 1: printf("C90\n"); break; case 2: printf("C99\n"); break; case 8: printf("C11\n"); break; } } |
When asked what this program outputs, ChatGPT only considers C11, and 'corrects' itself after I pointed out the C90 lexical behavior. Grok only considers the latest standard, and when asked about producing other outputs, runs gcc with various -std options to find the other cases.
Both LLMs used (Grok 4.6 and ChatGPT 5.5) handled all the language differences I tried. Will cheaper to use coding agents, using LLMs containing an order of magnitude fewer parameters, be as effective at handling obscure differences? We will have to wait and see.
Source line length before coding agents
Will coding agent generated source code contain the same consistent patterns of behaviors that appear in human written source?
A brief analysis would suggest that the answer is: Yes. LLM training data is human written code, and coding agents are generating code to implement the functionality that developers would have otherwise implemented themselves.
Some coding patterns are driven by historical accidents, or at least appear to be. A line of code has to be visible on the display seen by the person writing it. Consequently, a line of source containing more characters that can be displayed on a line are likely to be rare. The plot below shows the number of C/C++ source lines containing a given number of characters in early 2000 (red) and 2026 (green), and the number of lines containing a given number of tokens in 2000 (blue), lines are fitted exponentials, and vertical grey lines at 80 and 120 characters (common default value used for tab characters; code+data):
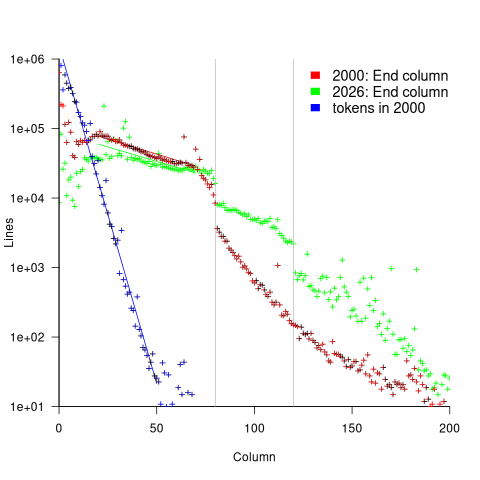
The dramatic drop in the number of lines of a given length, just below 80 characters, is consistent with the majority of character-based displays having lines containing 80 characters (the same as punched cards). A revolution in display technology happened between 2000 and 2026, namely CRTs were replaced by LCDs, significantly increasing possible display width. The decline in number of lines containing a given number of characters has decreased since 2000. In 2026, the 80 character line length break-point is less dramatic than in 2000, and the decline a lot less steep. Also, there appears to be a new break-point emerging at 120 characters; perhaps without LLMs the 80 character break-point would have gradually disappeared. While bit-mapped displays don’t have lines, existing practices live on and evolve.
The number of lines containing a given number of tokens, for the early 2000 measurements, decreases exponentially, with 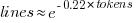 . Whitespace indentation adds characters, not tokens.
Most long lines are caused by indentation of the source code, e.g., indenting the body of an if-statement. Indentation is used to reduce the developer effort needed to understand statement clustering and sequencing.
The plot below shows the number of if-statements occurring at a given nesting level, along with regression fits, of the form 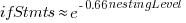 , to the 2026 Vim and SQLite data; the Linux data was better fitted by a power law (code+data):
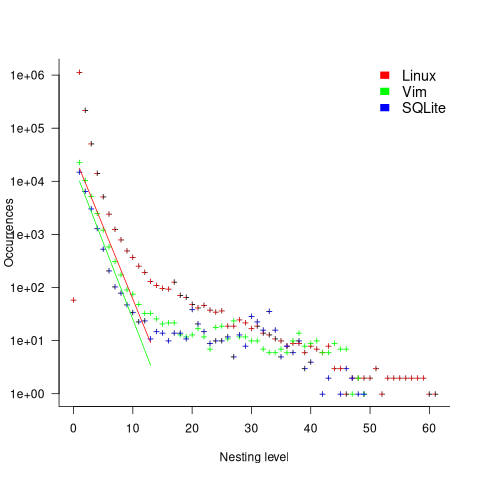
Some of the reasons developers write deeply nested code include: the nested code accesses local variables that would be a hassle to pass as function arguments, creating a function would interrupt their train of thought.
Deep nesting is often cited as bad practice, along with the usual unsubstantiated claims about it being error-prone, or hard to understand, or whatever.
Coding agents indent code because the training data contains indented code, and because the generated source is likely to be looked at and modified by developers. Attention based LLMs include information on the position of the token on a line, so given the contents of the training data, coding agents are unlikely to generate lines containing more than 80 characters.
If a time is reached when most developers don’t look at agent created code (few look at the assembly code generated by compilers), its visual layout becomes irrelevant. There are cost savings to be made by not indenting or limiting nesting depth. Indentation increases coding agent costs by consuming more tokens. Creating a new function consumes more tokens that simply generating a deeper nesting level.
If a developer wants to see indented source, they can always use a pretty printer.
A coding agent can be told not to indent, but given their training data do they indent internally and then remove it, i.e., an increase in token usage? This is another question to the growing list of Mechanistic interpretability problems.
Project implementation time savings using coding agents
To what extent do the significant savings made from using coding agents reduce the total cost of creating a software system?
The SEA Data Warehouse dataset contains detailed records of time spent in various phases of safety critical projects. Just what is needed to estimate an answer to this question, at least for safety critical software.
The development of typical commercial software differs from safety critical software in the amount of effort that goes into requirements, design, documentation, and testing. While the safety critical people claim that it’s all about the processes they follow, there is no evidence to show that any process is better than another. What matters is that the process ensures that the requirements, design, documentation, and testing are good enough for the intended use of the software.
When producing code is cheap, teams looking to be paid to create software systems are going to have to add value by delivering the kind of reliability and all encompassing application support that safety critical software is intended to provide.
The plot below shows, for the 289 projects that spent more than 2-days Code phase, the fraction of time spent in the most common project phases, ordered by fraction spent in Code phase (code+data):
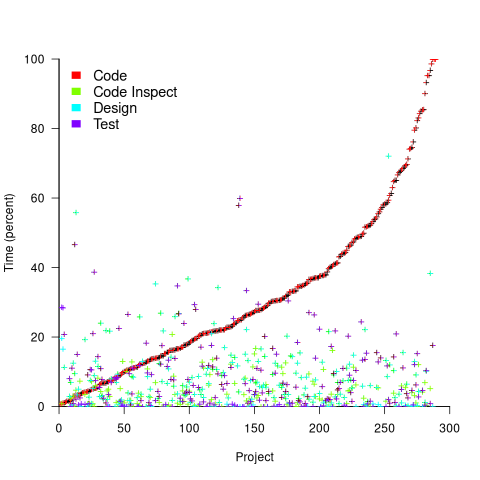
The average percentage of project time spent in the Code phase was 32% (does not include time spent in the Code review phase).
If we assume that coding agents reduce the time spent on coding by, say, 90%, and on all testing activities by, say, 50%, how much would total project time be reduced? The plot below shows, for the 289 projects, original project time (red) and estimated LLM project time (blue/green; code+data):
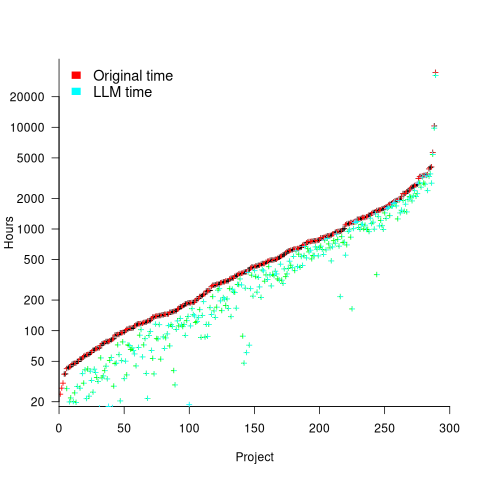
The general pattern visible is that as the number of project hours increases, the relative LLM saving shrinks. Around 10+ projects show substantial savings.
It’s possible that use of coding agents will increase the amount of time developers spend in the Code review phase (after any LLMs savings made in this phase). The 50% savings across all testing activities is very simplistic, and we will have to wait a few years for things to settle down and data to become available.
Around 10-15% of time is spent in Design, Design review, Design Inspection phases. Will LLMs save a significant amount of time for these phases, or should people continue to be hands-on for this work?
Experienced developers are well aware that coding agents have not removed the need for software developers. This post provided some data+analysis showing that developers are still needed, although the number of the people having this job title will decrease. Perhaps the software developer job title will not exist in 10-years, and this kind of work will be commonly known by another name.
Software effort estimation in 2026
It’s 2.5 years since my 2024 post summarizing what I knew about software effort estimation. For ongoing projects the role of estimation is as a planning tool, breaking down a large chunk of work into what are estimated to be small, well-defined, chunks. With two-thirds of estimates being within a factor of four (over or under) of the actuals, accuracy was not a primary goal.
The impact of coding agents capable of implementing these small tasks for peanuts is on developer staffing, not on the need for planning and breaking down work into connected small chunks.
Coding agents follow the specification they are given. Large, complicated programs will have large complicated specifications, which are likely to require a lot of human effort to create. For instance, the specification for the recent LLM generated C compiler
How long will it take to create a specification and how many iterations will be needed to create a good enough program? Estimation has not gone away, it has just moved upstream of the implementation. While specifications have existed millennia longer than software development, we are at the start of learning to use them to direct coding agents (the term vibe coding was created in February 2025). While logs of developer coding agent sessions are starting to be collected, it will take some years for patterns of practice to stabilize.
The process followed to estimate Function Points appears to be ideally placed to be extended to cover specification creation for coding agents.
Peanuts in bulk can be expensive. The novelty of much lower costs, when using coding agents, will soon wear off. Agent costs will become the new normal, which means there will be pressure to reduce them, and management will want estimates because the requirement to fill in boxes has not gone away.
Is agent token consumption purely a driven by the LLM(s) used and the selected configuration values? A recent study investigated the impact of the wording of the specification on the tokens spent by a selection of agents. The results showed that a specification containing bare user stories increased token spending by 30%. We will have to wait to find out whether the implications of this result (i.e., investing in more detailed user stories reduces token spending) replicates.
It would be very useful to have an estimate of likely token usage for a given specification, before any code is generated, or perhaps a real-time cost estimate during generation. One study found that current frontier models failed to accurately predict their own token usage (correlation of 0.39), humans predictions were equally poor.
Many projects don’t have a separate line item for testing costs, which often get bundled with implementation costs (the SEA Data Warehouse dataset separates out design/implementation/testing effort). Large projects may have people who work on integration and/or release testing.
When coding agents are used, testing is clearly a distinct piece of work separate from implementation. How effective is the specification used to generate the code at generating good enough tests? Current research is an extension of existing testing practices, rather than anything coding agent specific. A lot of existing research has focused on unit testing, and of course models have been fine-tuned for unit testing.
Implementation cost reductions have brought N-version programming into the realm of consideration for some projects.
Will the way developers work change to be like tradesmen who are hired to install a new fitted kitchen or bathroom? With developers installing new application functionality specified by the client. Perhaps some will be more like builders hired to make structural changes to a house, while others will do small jobs, like plumbers, electricians and carpet fitters.
As always, some researchers fail to move on when the world changes and continue to publish papers that use LLMs to estimate human task implementation time.
Number of projects worked on concurrently
Developers working for companies whose business is project based are often involved with multiple projects at the same time. If one project is held up, they have other projects to work on (reducing days when there is no project for them to book their time to).
How many software projects might a developer be working on at any time, and how is their time distributed across projects?
I was hoping that the SEA Data Warehouse dataset would provide some answers. However, while it contains detailed task data on 1,211 software projects, many of the people involved on these projects also worked on projects that are not included in the dataset (or they only worked a few hours a day, or the data is not as complete as claimed).
The 2,271 distinct people in the dataset worked on a total of 210,088 person days, working an average of 190 minutes (3.2 hours) per day. The plot below shows the number of minutes worked on each of the 210,088 person days, in sorted order (code+data):
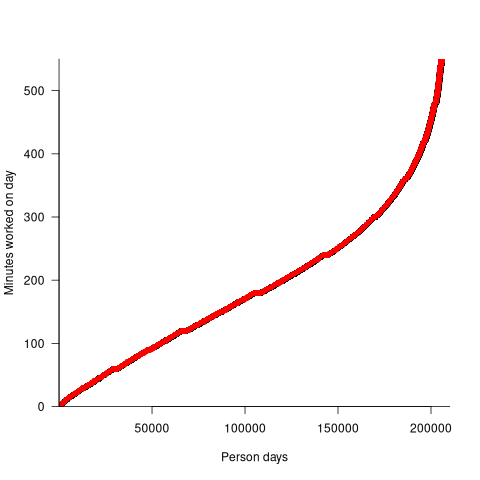
A 7.5-hour work day contains 450 minutes; what were they doing during the other 260 minutes each day? If people were not working on one of the projects in the dataset, they were presumably working on project(s) that are not in the dataset.
Within the available data, how many projects were individuals working on during various time intervals? The plot below shows the percentage of time intervals (there are more days in the year than weeks, and more weeks than months, and to make the plot easier to interpret the counts for each time interval has been normalised) where a given number of projects were worked on by an individual during a particular time interval, for day/week/month intervals, with fitted exponential models (exponents are: -2.8, -2.2, and -1.6, respectively; code+data):
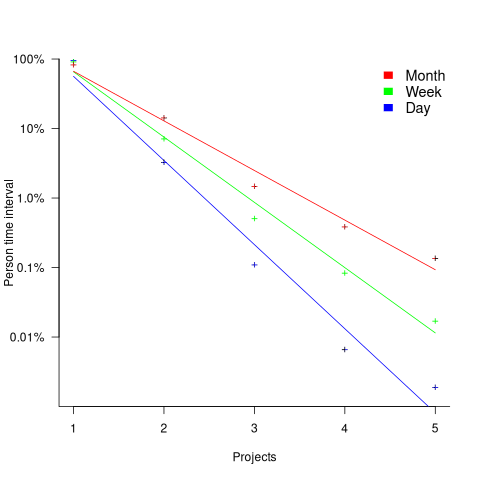
For the 1-project case, the percentage values are higher for days than weeks, and higher for weeks than months. However, the approximate nature of the fitted regression lines happens to have this the order reversed.
The plotted values are a lower bound for the number of projects an individual worked on within any of the time intervals. The average number of minutes worked per day implies that most people are working on at least two projects every day.
Recent Comments